

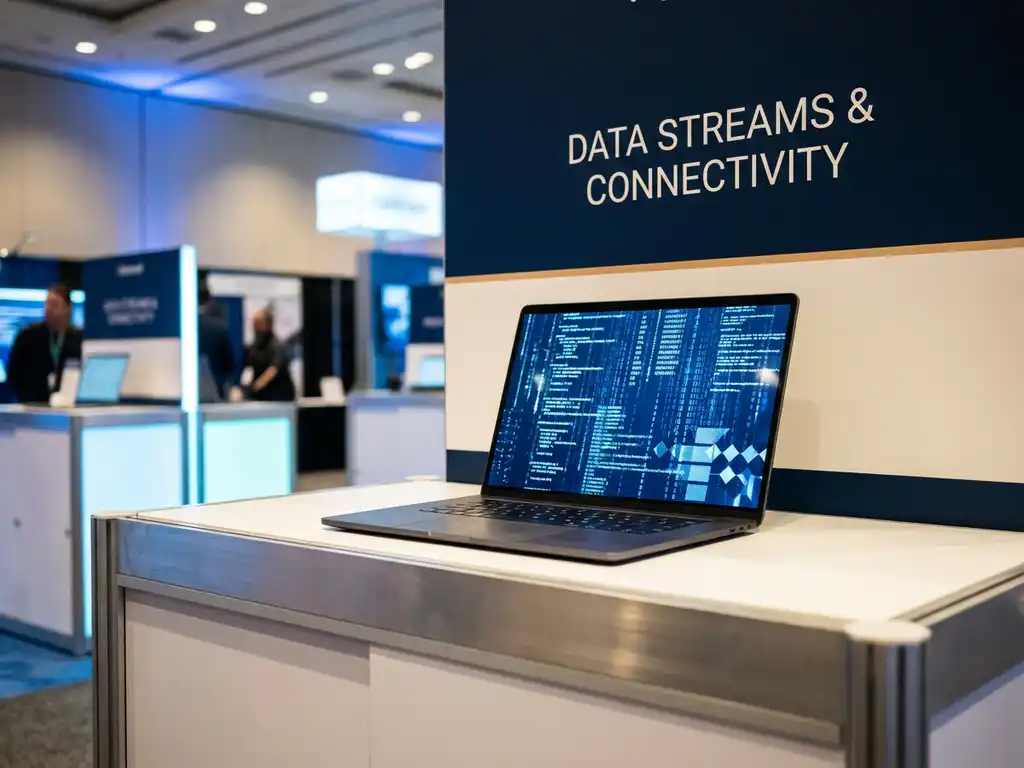
Yes, Openindex is showcasing AI-driven data extraction at Data Expo Utrecht in 2026. We are presenting our latest advances in intelligent web crawling, automated data collection, and Crawling as a Service to B2B audiences who depend on reliable, large-scale data pipelines. Read on to explore the key questions surrounding AI-powered data extraction and what it means for your business.
What is Openindex showcasing at Data Expo Utrecht?
At Data Expo Utrecht 2026, we are presenting our full suite of AI-driven data extraction and web scraping solutions, including our Crawling as a Service offering, advanced search APIs, and intelligent indexing tools. Our focus is on demonstrating how organizations can collect, structure, and activate large volumes of web data without building costly infrastructure in-house.
The showcase highlights how our technology handles millions of URLs at scale while maintaining data quality and legal compliance with regulations such as GDPR. Visitors can see live demonstrations of how a single line of JavaScript can embed a fully functional search engine into any website, and how our crawling pipelines deliver clean, structured datasets directly into client systems. For B2B buyers evaluating data infrastructure partners, the expo is a practical opportunity to see these capabilities in action rather than simply reading about them on a product page.
How does AI-driven data extraction actually work?
AI-driven data extraction works by combining traditional web crawling with machine learning models that can identify, classify, and structure relevant content automatically. Instead of relying solely on rigid, hand-coded rules to parse web pages, AI models adapt to variations in page layout, content type, and data format, making extraction far more resilient and accurate across diverse sources.
The process typically follows several stages:
- Discovery: A crawler systematically navigates websites, following links and mapping content across domains.
- Parsing: AI models identify which parts of each page contain relevant data, even when page structures vary significantly.
- Classification: Extracted content is categorized and tagged, for example as product listings, news articles, property records, or financial data.
- Indexing: Structured data is stored in a searchable index, often powered by technologies such as Apache Solr or Elasticsearch, ready for querying or integration.
- Delivery: Clean datasets are delivered via API, data feed, or direct system integration.
The AI layer is what separates modern data extraction from older scraping approaches. It handles edge cases, detects structural changes on source websites, and reduces the manual maintenance burden that traditionally made large-scale scraping expensive and fragile.
What industries benefit most from AI data extraction?
The industries that benefit most from AI-driven data extraction are those that depend on continuously updated, large-scale external data to make competitive decisions. E-commerce, real estate, finance, government, and market research are among the clearest beneficiaries because each sector relies on aggregating information from many sources quickly and accurately.
In e-commerce, businesses use automated data collection to monitor competitor pricing, track product availability, and enrich their own product catalogues. Real estate platforms aggregate property listings from multiple sources to build comprehensive market overviews. Financial services firms extract news, regulatory filings, and market signals to support investment and risk decisions. Government bodies and public sector organizations use crawling to index public information and improve citizen-facing search. Market research firms depend on web data to track trends, brand sentiment, and competitive landscapes across industries.
What these sectors share is a need for data that is fresh, structured, and delivered reliably at scale. Manual collection simply cannot keep pace, which is why AI-powered extraction has become a foundational capability rather than a nice-to-have.
How does Crawling as a Service differ from in-house scraping?
Crawling as a Service differs from in-house scraping in that the entire data collection infrastructure, maintenance, and delivery are managed externally by a specialist provider. Instead of building and operating your own crawlers, you receive clean, structured data as a feed or via API, without worrying about infrastructure costs, technical failures, or keeping pace with changes on source websites.
In-house scraping requires significant ongoing investment. Teams must build crawlers, maintain them as websites change their structure, handle IP blocking and rate limiting, manage server infrastructure, and ensure compliance with data privacy regulations. For many organizations, this creates a hidden operational burden that grows as data requirements scale.
With a managed crawling service, these responsibilities shift to the provider. The key practical differences are:
- Maintenance: The provider handles all updates when source sites change, not your internal team.
- Scalability: Infrastructure scales to handle millions of URLs without additional investment on your side.
- Compliance: A reputable provider builds GDPR-compliant and ethically responsible data collection into the service by default.
- Speed to value: You receive usable data faster, without a lengthy build phase.
- Focus: Your team concentrates on using data rather than collecting it.
For most B2B organizations, Crawling as a Service delivers a better return on investment than maintaining proprietary scraping infrastructure, particularly when data needs span multiple domains or require frequent updates.
Why are data expos important for B2B tech buyers?
Data expos are important for B2B tech buyers because they compress months of vendor research into a focused environment where decision-makers can compare solutions, ask technical questions directly, and see live demonstrations side by side. For complex technology purchases like data extraction platforms, this direct access to providers and working prototypes significantly reduces evaluation risk.
Beyond product discovery, expos like Data Expo Utrecht serve as a pulse check on where the industry is heading. Buyers can identify emerging capabilities, understand how peer organizations are solving similar problems, and build relationships with providers before committing to a procurement process. For technology investments that will underpin core business operations, that context is genuinely valuable.
Expos also create a natural opportunity to pressure-test vendor claims. A live demonstration of AI-driven web scraping handling real-world data at scale tells a buyer far more than a white paper. For B2B organizations evaluating data infrastructure partners, the expo floor is one of the most efficient places to move from awareness to informed shortlisting.
How Openindex helps with AI-driven data extraction
We bring together deep expertise in search, crawling, and data engineering to deliver end-to-end data extraction solutions tailored to your organization’s specific needs. Whether you require a managed crawling service, a custom search API, or a fully integrated data pipeline, we build solutions that scale reliably and comply with GDPR from the ground up.
Here is what working with us looks like in practice:
- Crawling as a Service: We manage the entire collection process and deliver clean, structured data directly to your systems.
- Custom search solutions: We integrate powerful search engines into your website or internal knowledge base using Apache Solr, Elasticsearch, and related open-source technologies.
- API-first delivery: Data is accessible via well-documented APIs, making integration into your existing applications straightforward.
- Sector expertise: We have hands-on experience across e-commerce, real estate, finance, government, and market research, so we understand the data challenges specific to your industry.
- Scalable infrastructure: Our solutions handle millions of URLs without performance degradation, supporting your growth without requiring infrastructure reinvestment.
If you met us at Data Expo Utrecht or are exploring AI-driven data extraction for the first time, we would love to talk through what is possible for your organization. Get in touch with us to start the conversation.
Frequently Asked Questions
Can Openindex integrate with our existing data infrastructure?
Yes. Openindex delivers data via well-documented, API-first integrations, making it straightforward to connect with your existing applications, databases, or data pipelines. Whether you use cloud-based storage, a data warehouse, or custom internal systems, our solutions are built to fit into your current stack without requiring a full rebuild.
How quickly can we get started with Crawling as a Service?
Onboarding is significantly faster than building in-house, since you skip the infrastructure setup and crawler development phases entirely. After an initial scoping conversation to define your data requirements, sources, and delivery format, most clients receive their first structured datasets within days rather than weeks.
How does Openindex ensure compliance with GDPR when collecting web data?
GDPR-compliant data collection is built into our service by default, not added as an afterthought. We follow ethical crawling practices, respect robots.txt directives, and only collect publicly available data, ensuring your organization can use the data we deliver without taking on unnecessary legal risk.
Will the service still work if source websites change their layout or structure?
Yes. One of the core advantages of AI-driven extraction over traditional scraping is its resilience to structural changes. Our models detect and adapt to layout changes on source sites automatically, and our team handles any necessary updates, so your data feed remains consistent without any action required on your end.