

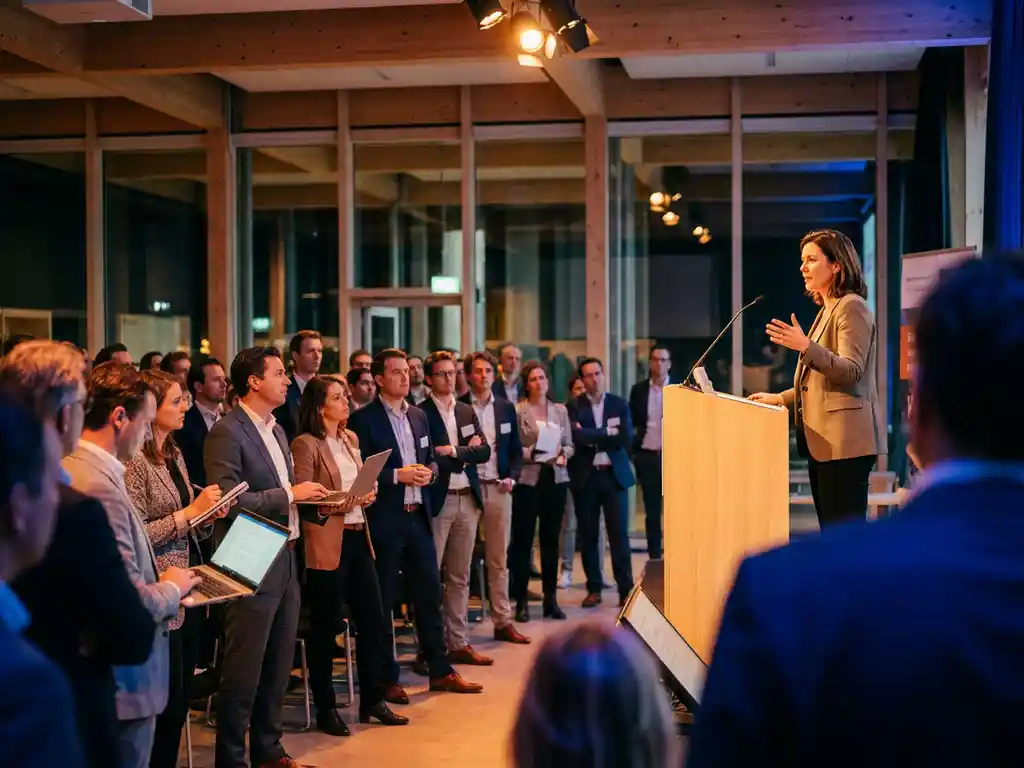
Openindex is giving a talk at Data Expo Utrecht. We are participating in this leading Dutch data conference to share our expertise in search technology, web crawling, and data extraction with a professional audience of data engineers, architects, and business intelligence specialists. Read on to find out what we cover, why it matters, and how you can connect with us at the event.
What is Data Expo Utrecht and who attends it?
Data Expo Utrecht is one of the Netherlands’ most prominent annual gatherings for data professionals, bringing together practitioners, vendors, and decision-makers from across the data and technology landscape. The event serves as a hub where organizations share knowledge, explore emerging tools, and discuss the practical challenges of working with large-scale data in 2026.
Attendees typically include data engineers, software architects, product managers, and business analysts who work with data pipelines, search infrastructure, and analytics platforms on a daily basis. The audience spans industries such as e-commerce, finance, government, real estate, and market research, which are precisely the sectors where reliable data collection and search capabilities have the greatest operational impact.
Beyond the technical crowd, Data Expo Utrecht also draws executives and digital transformation leads who are evaluating new solutions for their organizations. This mix of hands-on practitioners and strategic decision-makers makes it an ideal setting for conversations about real-world challenges in data indexing, crawling, and search relevance.
What topics does Openindex cover in its talks?
In our talks at data conferences like Data Expo Utrecht, we focus on the practical intersection of search technology, web crawling, and structured data extraction. Our goal is always to give attendees actionable insights they can apply directly to their own data challenges, rather than delivering abstract theory.
The topics we typically address include:
- Search relevance and indexing at scale: How to build search solutions that return accurate, meaningful results across millions of documents or URLs using technologies like Apache Solr, Lucene, and Elasticsearch
- Web crawling architecture: The design decisions behind scalable crawling systems, including how tools like Apache Nutch and Hadoop handle large, distributed data collection tasks
- Web scraping and data extraction: Practical approaches to extracting structured data from unstructured sources, and how to do so in a way that is reliable, maintainable, and legally compliant
- Crawling as a Service: How organizations can offload the complexity of data collection entirely, receiving clean, ready-to-use data feeds without managing the underlying infrastructure themselves
- Open source tooling in production: Lessons learned from deploying open source search and crawling solutions in demanding environments across sectors like e-commerce and government
We bring a practitioner’s perspective to every session. Because we work directly with clients on custom search and crawling implementations, the examples and challenges we discuss are drawn from real projects rather than hypothetical scenarios.
Why do data professionals attend talks on search and crawling?
Data professionals attend talks on search and crawling because these two disciplines sit at the foundation of almost every data-driven application. Without reliable data collection and effective search infrastructure, downstream analytics, machine learning pipelines, and business intelligence tools are only as good as the incomplete or poorly indexed data feeding them.
Several factors make these sessions particularly valuable at a data conference:
- Complexity is growing: The volume and variety of data sources organizations need to monitor and index have expanded significantly. Keeping up with best practices in crawling architecture and search tuning requires continuous learning.
- Compliance requirements are tightening: GDPR and other data privacy regulations affect how organizations collect and store web data. Talks from practitioners who navigate these requirements daily offer concrete guidance that documentation alone cannot provide.
- Open source ecosystems evolve rapidly: Tools like Elasticsearch and Apache Solr release updates that change how search relevance, performance, and scalability are achieved. Conference talks help professionals stay current without spending weeks on documentation.
- Peer learning is irreplaceable: Hearing how another team solved a crawling bottleneck or improved search precision in production is often more useful than any tutorial, because the context and constraints are recognizable.
For organizations evaluating whether to build search and crawling capabilities in-house or work with a specialist, these sessions also provide a clearer picture of the real effort and expertise involved, helping teams make more informed build-versus-buy decisions.
How can attendees connect with Openindex at the event?
Attendees can connect with us at Data Expo Utrecht by approaching us directly after our talk, when we are always happy to continue the conversation and answer questions specific to your organization’s situation. We also make time during breaks and networking sessions to speak with professionals who want to explore how search and crawling solutions could fit their particular use case.
If you want to prepare before the event, reaching out in advance is a great way to arrange a dedicated conversation during the day. This is especially useful if you have a specific project or challenge in mind and want to make the most of the time available at the conference.
Whether your interest is in a standalone search implementation, a managed crawling setup, or a broader data extraction project, we enjoy talking through the options with people who are working on real problems. Data Expo Utrecht is exactly the kind of environment where those conversations lead somewhere useful.
How Openindex helps with search, crawling, and data at events like Data Expo Utrecht
We do more than give talks at data conferences. As a Dutch technology company specializing in advanced search and crawling solutions, we help organizations across e-commerce, finance, real estate, government, and market research build the data infrastructure they need to operate effectively. Here is what we bring to the table:
- Custom search solutions built on Apache Solr, Lucene, and Elasticsearch, tailored to your content type and user needs
- Scalable web crawling using Apache Nutch and Hadoop-based architectures capable of handling millions of URLs
- Web scraping and data extraction services that deliver clean, structured data from complex or dynamic sources
- Crawling as a Service and Data as a Service offerings where we manage the entire collection process and deliver data as feeds or direct integrations
- Site search as a simple integration, deployable on any website with a single line of JavaScript
- GDPR-compliant data practices built into every project from the start
If you are attending Data Expo Utrecht and want to discuss what we can do for your organization, or if you simply want to continue the conversation after our talk, we would love to hear from you. Get in touch with us and we will find a moment to connect.
Frequently Asked Questions
Can I speak with Openindex at Data Expo Utrecht even if I don't attend the talk?
Yes, you can connect with the Openindex team during breaks and networking sessions throughout the day, not just after the talk. Reaching out in advance to schedule a dedicated conversation is also a great option if you have a specific project in mind.
Is Crawling as a Service suitable for organizations without an in-house data engineering team?
Absolutely. Crawling as a Service is specifically designed for organizations that want clean, structured data without managing the underlying infrastructure themselves. Openindex handles the entire collection process and delivers data as ready-to-use feeds or direct integrations.
How does Openindex ensure its web crawling and data extraction services are GDPR-compliant?
GDPR-compliant practices are built into every Openindex project from the start, not added as an afterthought. This means data collection, storage, and delivery are all structured to meet Dutch and EU privacy requirements by design.
What is the quickest way for a company to get started with Openindex's search or crawling solutions?
The fastest route is to get in touch directly via the Openindex contact page and describe your use case or data challenge. From there, the team can quickly assess whether a custom search solution, managed crawling setup, or a simpler integration like their single-line JavaScript site search is the right fit.