


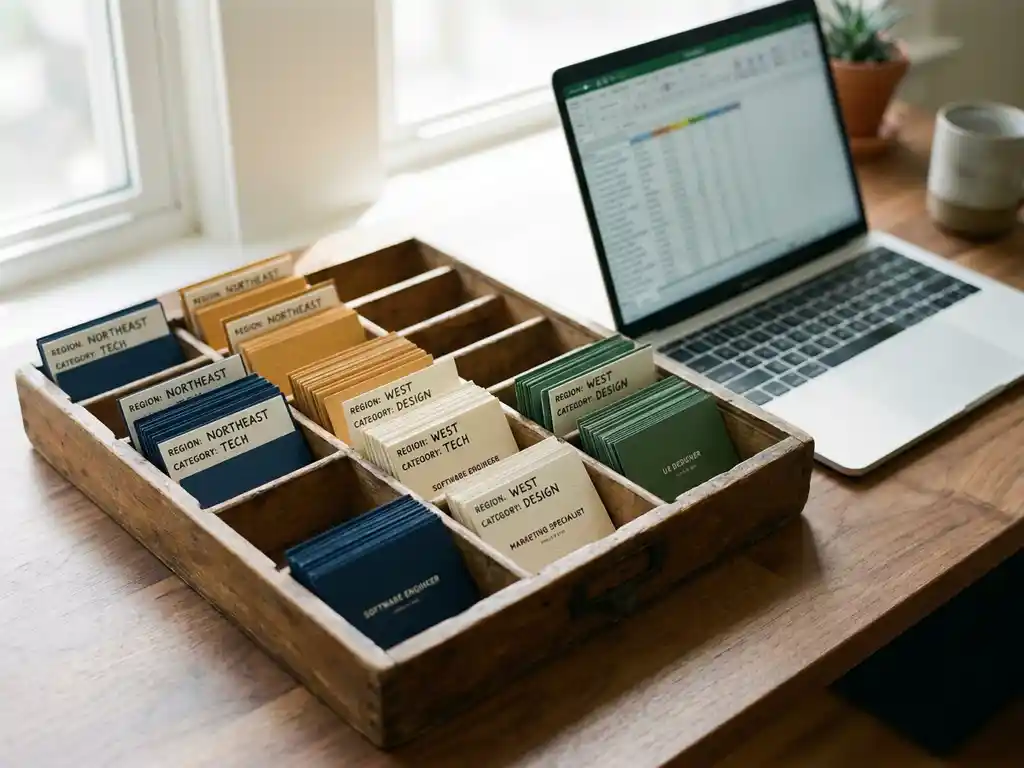
You can automatically categorize vacancies by industry and region by extracting structured data points from job postings, such as job title, required skills, company sector, and location fields, then applying classification logic through machine learning models, taxonomy matching, or rule-based systems. This approach works at scale across thousands of job postings simultaneously and is especially valuable for job boards, recruitment platforms, and market research teams that need clean, structured vacancy data. The sections below walk through each layer of the process, from raw data extraction to long-term data quality.
What data points in a vacancy make categorization possible?
The data points that make automated vacancy categorization possible are job title, job description text, required skills, company name, sector tags, and location fields such as city, region, postal code, or country. These fields provide the raw signals that classification systems use to assign each posting to the correct industry and geographic category. The richer and more consistent these fields are, the more accurate the categorization becomes.
Not all vacancy sources structure their data the same way. Some job boards expose clean, labeled fields through an API. Others publish postings as unstructured HTML pages where the job title, location, and description are embedded in page content without explicit labels. In both cases, the categorization pipeline needs to identify and extract the relevant signals before any classification can happen.
The most reliable signals for industry classification are job title and required skills. A posting mentioning “React,” “TypeScript,” and “CI/CD pipelines” points strongly toward the software development sector, even if the employer is a logistics company. For regional classification, the most direct signals are explicit location fields, but these are often inconsistent. A posting might say “Amsterdam” in one field and “remote, Netherlands” in another, requiring the system to resolve the conflict intelligently.
Secondary signals such as company name, salary range, and contract type can reinforce classification decisions when primary signals are ambiguous. A well-designed data pipeline captures all of these fields and preserves them for downstream classification logic.
How does automated industry classification of job postings work?
Automated industry classification of job postings works by mapping extracted text fields, primarily job title and description, against a predefined industry taxonomy using either rule-based matching, machine learning models, or a combination of both. The system assigns each vacancy a category label such as “Finance,” “Healthcare,” or “IT and Software” based on how closely the posting’s content aligns with each category’s defining terms and patterns.
Rule-based systems use keyword lists and pattern matching. If a job title contains “accountant,” “controller,” or “auditor,” the system maps it to Finance. These systems are fast, transparent, and easy to maintain for well-defined categories. Their weakness is coverage: they struggle with ambiguous titles like “Operations Manager” that appear across multiple industries.
Machine learning classifiers, trained on labeled vacancy datasets, handle ambiguity much better. A model trained on tens of thousands of annotated job postings learns contextual signals that go beyond simple keyword matching. It can distinguish a “Sales Manager” in retail from one in enterprise software based on the surrounding description text. The trade-off is that these models require quality training data and periodic retraining as job market language evolves.
In practice, most robust classification systems combine both approaches. Rule-based logic handles high-confidence cases quickly, while a machine learning model handles edge cases and ambiguous postings. A confidence threshold determines which postings get auto-classified and which get flagged for review or secondary processing.
How do you automatically detect the region of a vacancy?
You automatically detect the region of a vacancy by extracting location strings from the posting and resolving them against a geographic reference database, such as a geocoding API or a structured location taxonomy. The system identifies place names, postal codes, or region labels in the vacancy text and maps them to standardized geographic units like province, state, or country.
The first step is extraction. Location data appears in different places depending on the source: a dedicated location field, the job title (“Marketing Manager Amsterdam”), the body text, or a structured schema tag embedded in the page HTML. A well-built scraper captures all of these and passes them to a normalization layer.
Normalization resolves variations in how the same place is written. “Den Haag,” “The Hague,” and “‘s-Gravenhage” all refer to the same city. A geographic reference database maps these variants to a single canonical entry and attaches the correct region, province, and country codes. For postal codes, the mapping is often more straightforward and more reliable than free-text place names.
Remote work postings add complexity. A vacancy labeled “Remote, Netherlands” belongs to a national category but not a specific regional one. Classification systems typically handle this with a dedicated “remote” flag alongside a country-level assignment, rather than forcing an inaccurate regional label.
What tools and technologies handle vacancy categorization at scale?
The tools and technologies that handle automated job posting categorization at scale include web crawlers for data collection, natural language processing libraries for text analysis, geocoding APIs for location resolution, and search and indexing platforms such as Apache Solr or Elasticsearch for storing and querying the classified data. These components work together in a pipeline that moves vacancy data from source to structured, searchable output.
Data collection and extraction
Web crawlers built on frameworks like Apache Nutch collect vacancy pages from job boards and employer websites. Scrapers extract structured fields from raw HTML using CSS selectors or XPath patterns. For sources that offer APIs, direct API integration is faster and produces cleaner data. The output at this stage is raw vacancy records with extracted fields ready for processing.
Classification and enrichment
NLP libraries such as spaCy or Hugging Face Transformers power text-based industry classification. For location detection, geocoding services like Google Maps Geocoding API or open alternatives like Nominatim resolve place names to geographic coordinates and administrative regions. Classification models assign taxonomy labels, and the enriched records are then indexed into a search platform where they can be filtered, aggregated, and queried by industry and region.
For organizations running this at scale, job board data extraction through a managed crawling service removes the infrastructure burden. Rather than maintaining crawlers, parsers, and classification pipelines internally, the processed and categorized data is delivered directly as a structured feed.
What are the most common errors in automated vacancy classification?
The most common errors in automated vacancy classification are misclassified industry labels due to ambiguous job titles, incorrect or missing regional assignments caused by inconsistent location data, duplicate postings counted as separate vacancies, and outdated classifications when job market terminology shifts faster than the classification system is updated.
Ambiguous job titles are the leading source of industry misclassification. Titles like “Analyst,” “Consultant,” or “Manager” appear in nearly every sector. Without sufficient context from the job description, a classifier trained on title alone will assign these to whichever industry is most common in its training data, which may not match the actual posting.
Location errors often stem from incomplete or contradictory source data. A posting might list a headquarters city that differs from the actual work location, or use informal location labels that do not map cleanly to administrative regions. Remote and hybrid postings are particularly prone to location ambiguity.
Duplicate detection is a structural challenge in vacancy scraping. The same job posting frequently appears on multiple platforms, and without deduplication logic based on employer name, job title, posting date, and description similarity, the same vacancy gets counted multiple times in any analysis built on the data.
How do you keep categorized vacancy data accurate over time?
You keep categorized vacancy data accurate over time by scheduling regular re-crawls of vacancy sources, monitoring classification confidence scores to catch drift, updating taxonomy mappings when new job categories emerge, and running periodic audits that compare a sample of auto-classified postings against human-reviewed ground truth. Accuracy is not a one-time setup but an ongoing operational discipline.
Job market language evolves continuously. New roles like “Prompt Engineer” or “AI Safety Researcher” did not exist in most industry taxonomies a few years ago. A classification system that is not updated to recognize emerging job categories will either misclassify these postings or assign them to a catch-all “Other” bucket, degrading the usefulness of the data over time.
Monitoring confidence scores helps surface problems early. When a classifier’s average confidence on a category drops, it often signals that source data has changed, a job board has updated its posting format, or a new type of vacancy has entered the pipeline that the model has not seen before. Setting automated alerts on confidence thresholds allows teams to investigate and retrain before errors accumulate.
Re-crawling frequency should match the update rate of each source. High-volume job boards that publish hundreds of new postings daily need daily or even intraday crawls. Smaller niche sources may only need weekly updates. Aligning crawl schedules with source activity ensures the dataset stays current without wasting infrastructure resources.
How Openindex helps with automatic vacancy categorization
We build and operate the full data pipeline that makes automated vacancy categorization reliable at scale. Whether you need structured vacancy feeds organized by industry and region or a searchable index of job postings integrated directly into your platform, we handle the technical complexity so your team works with clean, classified data from day one. Here is what we bring to the process:
- Crawling and scraping at scale: We collect vacancy data from job boards, employer websites, and other sources using robust, fault-tolerant crawlers that handle format changes and anti-scraping measures.
- Industry and region classification: We apply rule-based and model-driven classification to assign accurate industry and geographic labels to each posting, using taxonomies tailored to your use case.
- Deduplication and data quality: We identify and remove duplicate postings across sources, ensuring your dataset reflects actual vacancy volume rather than inflated counts.
- Search and indexing integration: Using Apache Solr and Elasticsearch, we index classified vacancy data so it is immediately queryable by sector, region, job title, or any custom dimension you need.
- Ongoing maintenance: We monitor classification accuracy, update taxonomies as the job market evolves, and adjust crawl schedules to keep data fresh.
If you are building a job board, running labor market research, or need structured vacancy data to power a recruitment product, we would like to help you get it right. Contact us to discuss your specific requirements and find out how we can deliver the categorized vacancy data your project needs.
Related Articles
- What are practical examples of AI enrichment in data extraction?
- What does it cost to outsource vacancy data extraction in the Netherlands?
- Can I have job offers update in real time in my own system?
- What is the difference between scraping and data mining?
- What authentication methods work for API data extraction?




