

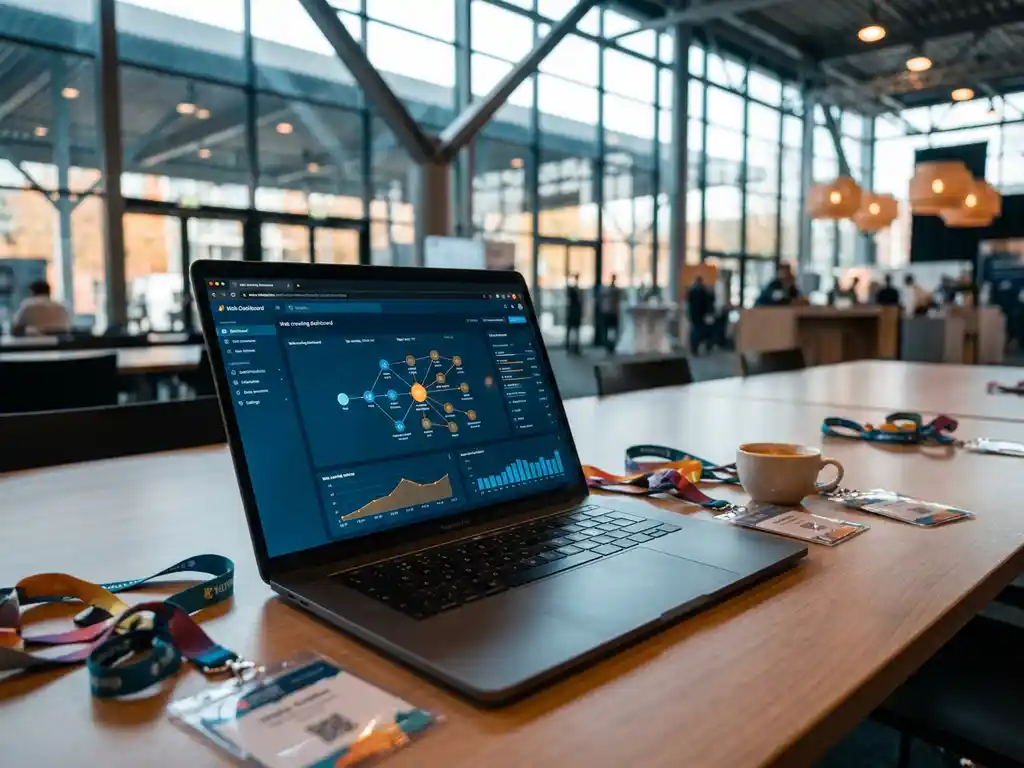
Yes, you can learn more about Crawling as a Service at Data Expo Utrecht. The event brings together data professionals, technology vendors, and decision-makers, making it one of the best places to explore how managed web crawling solutions can support your data strategy. Below, we cover the key questions you might have before attending.
What will be showcased about Crawling as a Service at Data Expo Utrecht?
At Data Expo Utrecht, visitors can expect live demonstrations, expert talks, and hands-on conversations about how Crawling as a Service works in practice. Exhibitors and speakers typically cover everything from large-scale data extraction pipelines to real-world applications across industries that depend on fresh, structured web data. It is an ideal setting to see CaaS in action rather than just reading about it.
Data Expo Utrecht gathers professionals from across the data ecosystem, which means the showcases tend to go beyond surface-level introductions. Attendees can explore how modern crawling platforms handle scheduling, deduplication, JavaScript rendering, and compliance with data privacy regulations like GDPR. Whether you are evaluating a solution for the first time or looking to upgrade an existing setup, the expo offers a concentrated opportunity to compare approaches and ask pointed technical questions directly to the people who build these systems.
Networking sessions alongside the main programme also give you access to practitioners who have already implemented CaaS in their organisations, offering candid insight into what works and what does not.
What is Crawling as a Service and how does it work?
Crawling as a Service (CaaS) is a managed solution in which a third-party provider handles the entire web crawling and data extraction process on your behalf, delivering structured data directly to your systems or applications. Instead of building and maintaining your own crawler infrastructure, you define what data you need, and the provider takes care of the rest.
The process typically works in three stages. First, you specify your target sources, the data fields you want extracted, and the frequency at which you need updates. Second, the CaaS provider deploys and manages the crawling infrastructure, navigating dynamic pages, handling authentication where applicable, and ensuring the data is cleaned and structured. Third, the extracted data is delivered to you as a feed, via an API, or integrated directly into your application.
A well-built CaaS platform also manages the technical complexity that makes in-house crawling difficult: rotating proxies, rate limiting, handling JavaScript-heavy pages, and staying within the legal and ethical boundaries of data collection. The result is a reliable, scalable data pipeline without the operational overhead.
Which industries benefit most from Crawling as a Service?
The industries that benefit most from Crawling as a Service are those that depend on large volumes of frequently updated external data to drive their products or decisions. E-commerce, real estate, finance, government, and market research are among the sectors where CaaS delivers the most consistent value.
- E-commerce: Price monitoring, competitor analysis, and product catalogue enrichment all require continuous data collection at scale.
- Real estate: Aggregating property listings, pricing trends, and neighbourhood data from multiple sources is a natural fit for managed crawling.
- Finance: Tracking market signals, news sentiment, and regulatory filings demands reliable, timely data extraction.
- Government and public sector: Monitoring public information sources, aggregating open data, and maintaining searchable knowledge bases benefit from automated crawling pipelines.
- Market research: Building datasets from across the web for trend analysis or consumer insight projects is far more efficient with a managed service than with an in-house team.
Any organisation that currently spends significant engineering time maintaining scrapers or dealing with broken data pipelines is also a strong candidate for CaaS, regardless of industry.
How does Crawling as a Service differ from building an in-house crawler?
The core difference between Crawling as a Service and an in-house crawler is where the operational responsibility sits. With CaaS, the provider owns the infrastructure, maintenance, and compliance burden. With an in-house crawler, your engineering team builds, scales, and continuously updates it as websites change and technical requirements grow.
Building your own crawler gives you full control over the logic and data flow, which can be valuable for highly specialised use cases. However, the hidden costs are significant. Crawlers break when target websites update their structure. Scaling to millions of URLs requires substantial infrastructure investment. Handling JavaScript rendering, bot detection, and GDPR compliance adds layers of complexity that demand ongoing attention.
CaaS removes those ongoing costs and redirects your team’s energy toward using the data rather than collecting it. For most organisations, the trade-off favours a managed service unless the crawling requirements are so unique that no external provider can meet them. The decision ultimately comes down to whether data collection is a core competency you want to own or an operational function you want to outsource.
Who should attend Data Expo Utrecht to learn about CaaS?
Anyone responsible for data strategy, engineering, or procurement within a data-intensive organisation should consider attending Data Expo Utrecht to explore CaaS options. This includes data engineers, product managers, CTOs, and business analysts who are evaluating how to improve their data pipelines or reduce the cost of maintaining in-house scraping infrastructure.
The expo is particularly relevant for professionals in e-commerce, real estate, finance, and market research who need reliable external data feeds as part of their core operations. It is also well suited for decision-makers who are early in their evaluation process and want to compare multiple vendors and approaches in a single location.
If your organisation is currently dealing with unreliable scrapers, slow data refresh cycles, or scaling challenges, Data Expo Utrecht offers a practical environment to explore solutions and speak directly with providers who can address those specific pain points.
How Openindex helps with Crawling as a Service
We are Openindex, a technology company from Groningen specialising in advanced search, crawling, and data extraction solutions. Our Crawling as a Service offering is built for organisations that need structured, reliable web data without the overhead of managing their own crawling infrastructure. Here is what we bring to the table:
- Fully managed crawling pipelines tailored to your specific data sources and update frequency
- Delivery of clean, structured data via API, feed, or direct integration into your application
- Expertise in Apache Solr, Elasticsearch, Apache Nutch, and other open-source technologies that power scalable data collection
- GDPR-compliant data collection practices built into every project
- Experience across e-commerce, real estate, finance, government, and market research
Whether you want to explore our CaaS solution before or after Data Expo Utrecht, we are happy to walk you through how it works for your specific use case. Get in touch with us and let us show you what managed web crawling can do for your organisation.
Häufig gestellte Fragen
Can I speak directly with Openindex at Data Expo Utrecht?
Yes, Data Expo Utrecht provides a great opportunity to meet the Openindex team in person. You can ask technical questions, discuss your specific data needs, and get a live walkthrough of their Crawling as a Service solution — all in one place.
How quickly can a Crawling as a Service solution be set up after the expo?
Onboarding timelines vary depending on the complexity of your data sources and delivery requirements, but most managed CaaS providers can get a basic pipeline running within days. Attending the expo and having detailed conversations upfront helps speed up the scoping process significantly.
Is Crawling as a Service suitable for smaller organisations or startups?
Absolutely. CaaS is often a better fit for smaller teams precisely because it removes the need to hire and maintain dedicated scraping engineers. You get enterprise-grade crawling infrastructure without the overhead, making it a cost-effective option at any scale.
What should I prepare before attending Data Expo Utrecht to get the most out of CaaS conversations?
Come with a clear picture of your current data pain points — which sources you need, how often you need updates, and what your existing pipeline looks like. The more specific you can be, the more useful and tailored the conversations with vendors like Openindex will be.